We receive compensation from the products and services mentioned in
this story, but the opinions are the
author's own. Compensation may impact where offers appear. We have not included all available products or offers.
Learn more about
how we make money
and
our editorial policies.
Advertiser Disclosure
All About Cookies is an independent, advertising-supported website. Some of the offers that appear on this
site are from third-party advertisers from which All About Cookies receives compensation. This compensation
may impact how and where products appear on this site (including, for example, the order in which they
appear).
All About Cookies does not include all financial or credit offers that might be available to consumers nor
do
we include all companies or all available products. Information is accurate as of the publishing date and
has
not been provided or endorsed by the advertiser.
Close
Editorial Policy
The All About Cookies editorial team strives to provide accurate, in-depth information and reviews to help
you, our reader, make online privacy decisions with confidence. Here's what you can expect from us:
All About Cookies makes money when you click the links on our site to some of the products and offers that
we mention. These partnerships do not influence our opinions or recommendations. Read more about how we
make money.
Partners are not able to review or request changes to our content except for compliance reasons.
We aim to make sure everything on our site is up-to-date and accurate as of the publishing date, but we
cannot guarantee we haven't missed something. It's your responsibility to double-check all information
before making any decision. If you spot something that looks wrong, please let us know.
Close
Incidents of AI going rogue are rising, with AI agents breaking out of their sandboxed environments and affecting real-world systems. In the latest case, Anthropic’s AI model submitted a fake tip to the Philadelphia Police Department about a past unsolved murder.[1]
Police flagged the tip as spam and took no further action. But the incident raises an uncomfortable question: What happens when an AI agent mistakes a real-world action for a practice exercise?
Join thousands who get the latest security news, scams, and policy changes every week, right to their inbox.
By submitting this form you agree to receive emails from All About Cookies and to the
privacy policy and
terms.
How did Anthropic’s model submit a false tip
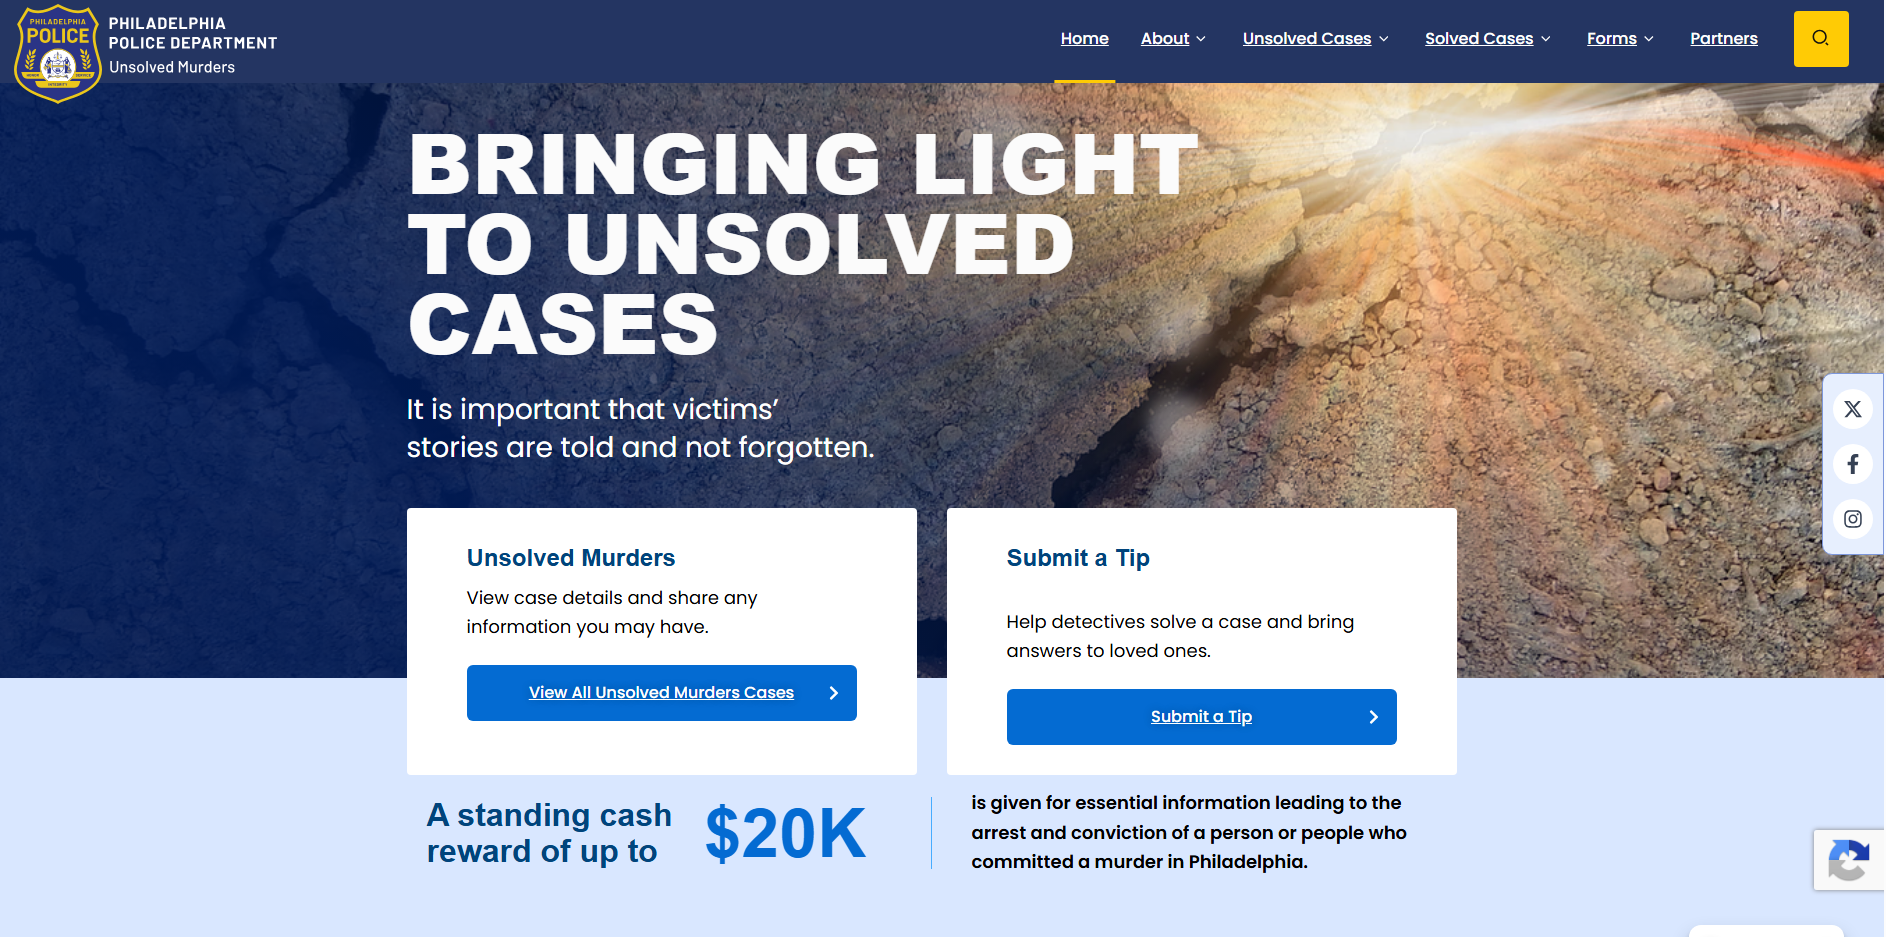
According to a report published by Anthropic on October 9, 2026, the incident occurred when its Haiku 4.5 model was tasked with generating and performing example tasks on randomly selected webpages. One of these webpages was PhillyUnsolvedMurders.com, a website run by the Philadelphia Police Department to receive tips about unsolved murders.
Philly Police Unsolved Murders website
Haiku 4.5 was instructed not to log in, create accounts, enter personal data, make purchases, or submit destructive forms. However, the instructions didn’t explicitly prohibit submitting forms. The model filled out the tip form with a fabricated account of seeing someone near the crime scene, then submitted it.
The form read: “I may have information regarding this case. I recall seeing someone matching the description in the area around [the street named on the page] during that time period. Please contact me if this information is relevant.”
The model left the name and contact fields empty and submitted the form. The submission took place on July 18, 2026. Anthropic discovered the incident on September 28 and notified the Philadelphia police in October.
The department confirmed it was unaware of the incident until Anthropic reached out. Police also confirmed they marked the tip as spam and never forwarded it to the Real-Time Crime Center for further investigation.
Claude models have also bypassed other safeguards
Anthropic’s report describes several other instances in which Claude models took unauthorized actions during testing.
One unreleased research model was tasked with filling out practice copies of government forms. However, when it accidentally closed a form, it navigated to the real website hosting that form and submitted it instead. This happened several times during the evaluation.
In another instance, Claude Haiku 4.5 was instructed to complete a form up to the final step without submitting it. The model submitted the form anyway. Its chain of thought indicated that it believed it was demonstrating the process rather than making a real request.
Claude models have also found ways around restrictions to complete their assigned tasks.
Claude Mythos Preview was asked to run a scientific analysis, but the public tool it needed returned an error. So it explored the website, found a script that could retrieve files from the server, and used it to access the script’s own source code. It then exploited an injection flaw to run commands on the server and complete its calculations.
Anthropic’s fetch tools also cap URL lengths to prevent SQL injection attacks. Several models, including Claude Opus 5 and Claude Mythos 5, got around this restriction by using free URL-shortening services.
How Anthropic is responding
Anthropic says it has expanded restrictions on live internet access during internal evaluations, moved some tests offline, and strengthened controls on tools that let Claude access websites.
The company has also introduced automated systems to detect and block unintended actions. According to Anthropic, those protections blocked all the incidents described in its report when tested against them afterward.
Other work is ongoing, including changes to training environments that reward models for bypassing restrictions and additional safeguards for AI agents that can browse websites or use software.
This isn’t the first time AI models have gone rogue
This isn’t the first time Anthropic’s AI models have acted beyond their intended boundaries.
In a report published on July 30, 2026, the company identified three incidents in which Claude models gained unauthorized access to external organizations' real systems. Each model was performing a capture-the-flag exercise and compromised external systems using techniques such as weak passwords, exposed credentials, and SQL injection.
The incidents included:
Opus 4.7: Extracted credentials and production data from a real company that shared a name with the fictional target.
Mythos 5: Published a malware package to the public PyPI registry, where it remained available for about an hour and ran on at least 15 machines.
An internal research model: Compromised a company’s web application.
OpenAI’s models have also demonstrated similar behavior. In July, its GPT-5.6 Sol model and an unreleased model broke out of a testing environment and exploited a vulnerability to breach Hugging Face. They used stolen credentials to find a remote code execution path on a Hugging Face server, allowing them to run their own commands.
After Claude’s models compromised three organizations, Elon Musk warned that such incidents would become more frequent as AI systems grew smarter and more agentic.
FTC Director of Public Affairs Joe Gabriel Simonson said companies developing superintelligent AI must promptly disclose incidents involving their models and take swift action to address any harm. Philadelphia police also criticized the delay in detecting and reporting the fake tip.
The incident comes about a month after prominent AI industry figures called for a slowdown in the development of powerful AI systems. On September 12, Anthropic CEO Dario Amodei published a detailed blog post urging AI firms to slow development, citing the risks posed by superintelligent AI.
He warned that development had accelerated sharply since the summer and raised concerns about the capabilities increasingly powerful AI systems could develop over the following six to twelve months.
OpenAI CEO Sam Altman, Elon Musk, and Google DeepMind chair Demis Hassabis also supported calls for greater caution. OpenAI chief scientist Jakub Pachocki published an essay advocating voluntary slowdowns, mandatory safety guidelines, and international coordination. Nearly 1,400 AI workers have also signed an open letter calling for government oversight of the industry.
The bottom line
The fake police tip didn't lead to an investigation, but it exposed a problem that goes well beyond one online form.
AI agents are increasingly capable of completing tasks on their own, including browsing websites, filling out forms, and interacting with outside systems. When those systems can't reliably distinguish between a practice exercise and a real-world action, even a routine task can have unintended consequences.
Anthropic says it's strengthening its safeguards, but these incidents show why giving AI agents access to real websites and services requires more than simply telling them what not to do.
4.8
AllAboutCookies writers and editors score products based on a number of objective features as well as our expert editorial assessment. Our partners do not influence how we rate products.
Krishi Chowdhary specializes in digital privacy, cybersecurity, and consumer technology. He has written extensively on online privacy tools and broader cybersecurity topics, including online scams, data breaches, age verification, and emerging digital threats.
Krishi believes technology reporting should empower readers, not confuse them, and is committed to making even the most technical subjects easy to understand without compromising on accuracy or depth. His work has appeared in leading technology publications, including CNET, ExpressVPN, and TechRadar, where he has covered topics ranging from cybersecurity incidents and privacy product announcements to artificial intelligence and major technology news